

Nothing is written until you save
Fix and convert return the new text. The assistant shows you the change, and you save it.
PyFluent doesn't need AI, which is why it's fast and inexpensive. When you write Python with Cursor or Claude, the MCP server lets your assistant check its code against the whole directory and fix anti-patterns in seconds—before anything hits GitHub.
select().mart.member_bands. Nothing is saved yet.
  scored.write.mode("overwrite").saveAsTable("mart.member_bands")
- saved = spark.table("mart.member_bands")
+ # later steps use scored
The loop fix adds a
plan_id column to mart.plan_scores, so it needs your call. Accept it?
.sort('plan') so the group order matches pandas.
- df = df[df["amount"] > 0]
+ df = df.filter(pl.col('amount') > 0)
- top = df.groupby("plan")["amount"].sum().reset_index()
+ top = df.group_by('plan').agg(pl.col('amount').sum()).sort('plan')
Vibe coding, with a safety net
Data code is full of details a model has to recall: which Polars release renamed what, which Spark pattern rescans a table. PyFluent turns recall into lookup, so the draft your assistant writes gets checked by something that doesn't guess.
| Task | AI assistant alone | With PyFluent over MCP |
|---|---|---|
| pandas to Polars | Rewrites by hand and can change group order or null handling. | Deterministic conversion, with .sort() added to keep pandas group order. |
| PySpark and Python upgrades | Remembers whichever version it saw most. | scan_upgrade lists exactly which APIs change from your version to the target. |
| Wasteful Spark code | Reviews the file you pasted. | 100+ static rules, each labeled proven, likely or unknown. |
| Across a whole directory | Limited to the files you paste into the prompt; misses helper & config links. | Continuous whole-directory lineage in seconds, execution stages, and cycle detection. |
| Did the move hold? | It looks right, so it reads right. | Verify checks dataset reads and writes and column lineage. |
8 tools
Datasets, lineage, run order and findings across files.
assess_pythonFind slow or risky Spark, Polars and pandas patterns it just wrote.
optimize_pythonApply the 8 automatic rewrites, plus findings you accept by id.
fix_pythonpandas, PySpark, Polars and Snowpark, with what needs review.
convert_pythonBreaking changes from PySpark 2.4 to 4.x and Python 3.7 to 3.15.
scan_upgradeStatic check of reads, writes and column lineage, before and after.
verify_migrationMigration waves and a Databricks bundle skeleton from dependencies.
plan_lakebridge_wavesExport the analysis as a workspace document for planning tools.
export_workspaceYou stay in control
Fix and convert return the new text. The assistant shows you the change, and you save it.
auto applies on its own, review needs you to pass the finding id, and manual is for you to decide.
PyFluent reads source on your machine. It doesn't execute it or connect to your data, clusters or accounts.
Set up in seconds
The PyPI package is coming. Email us for an early build today.
Paste the block into .cursor/mcp.json or your Claude Desktop config. It runs over stdio, or over HTTP with --http PORT.
A Cursor rule ships with PyFluent, so the assistant knows when to call the tools.
{
  "mcpServers": {
    "pyfluent": {
      "command": "pyfluent-mcp",
      "args": []
    }
  }
}
Prefer to review yourself?
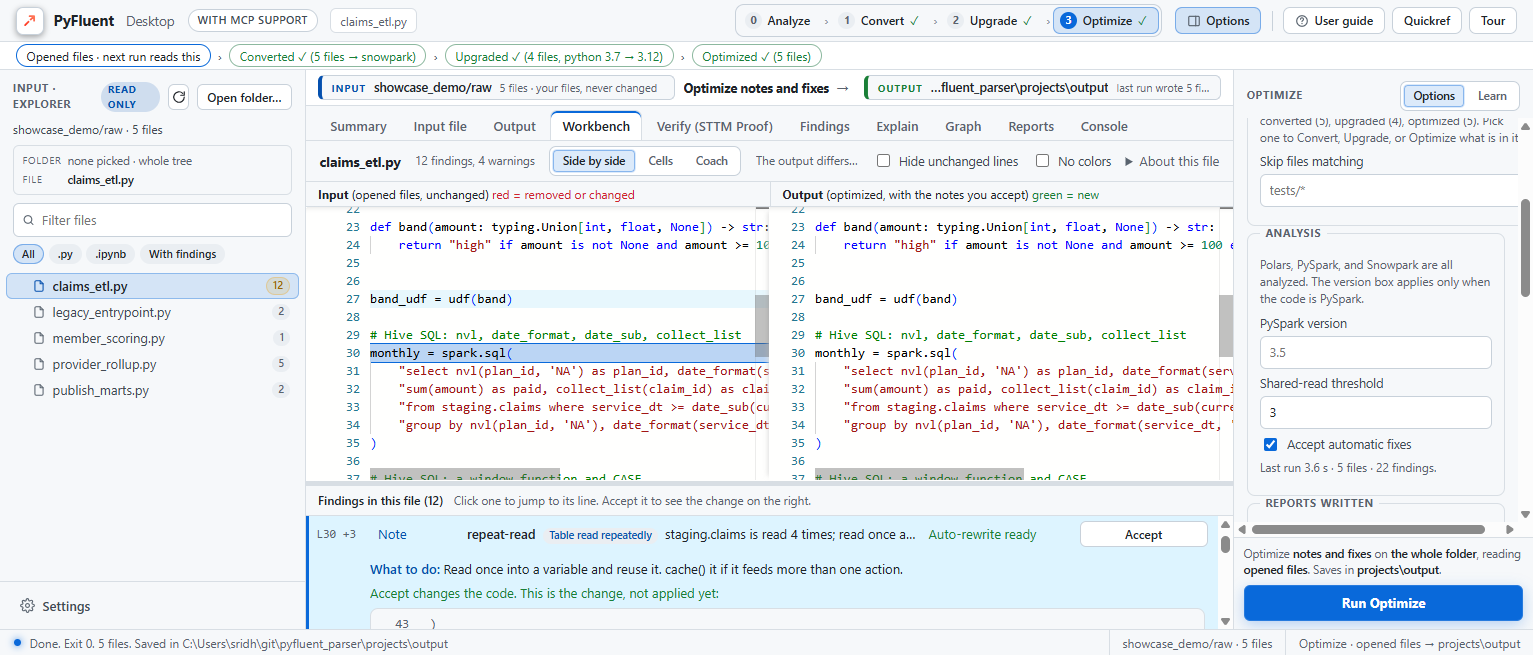
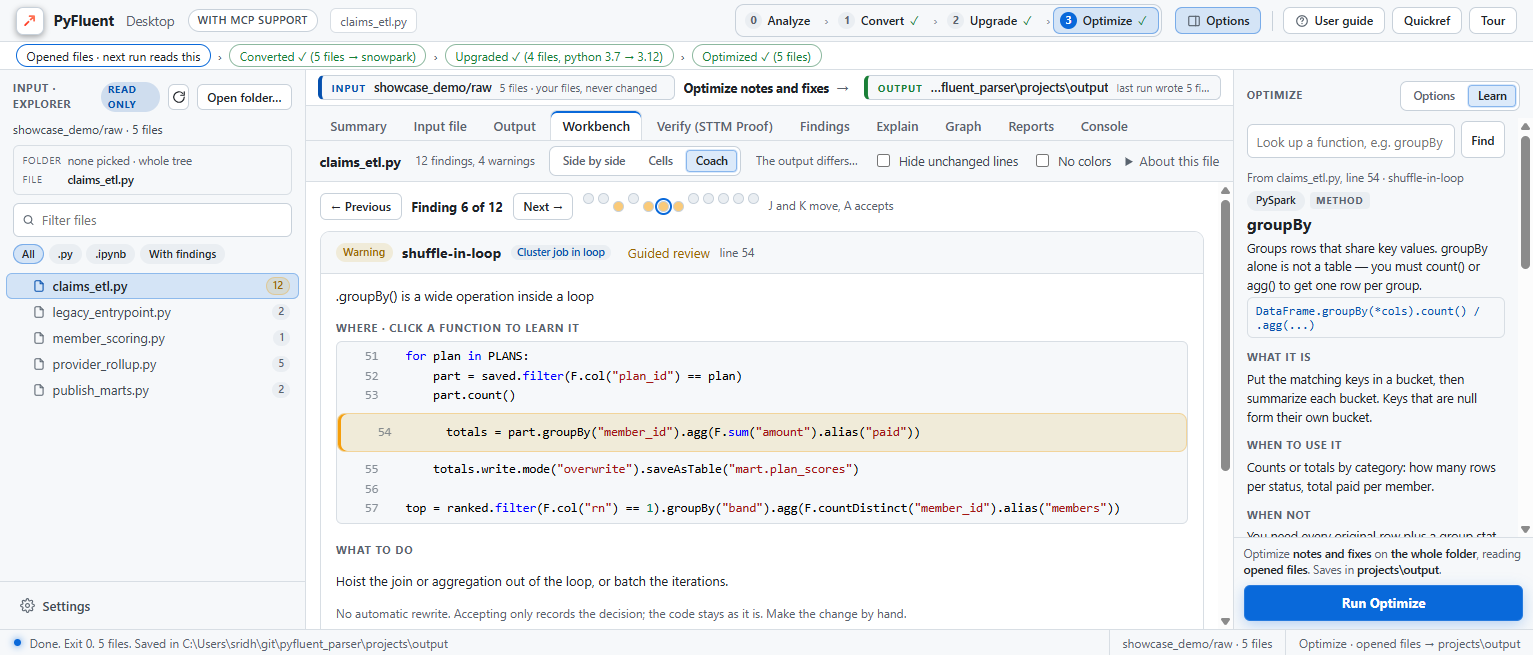
Side-by-side, Cells and Coach views with J/K/A review keys, and a Learn panel that opens a worked example for any call you click. Polars version upgrades run here and in the CLI today.
Shipping next
Dashed cards are on the roadmap, not released.
Block the same findings before a commit or in a pull request, with SARIF annotations.
Findings and quick fixes in the editor, with no assistant needed.
Find and install PyFluent from an MCP directory.
No AI required, no token bill. Tell us your stack and we will get you an early build.